Understanding Database Normalisation: A Practical Guide for Beginners
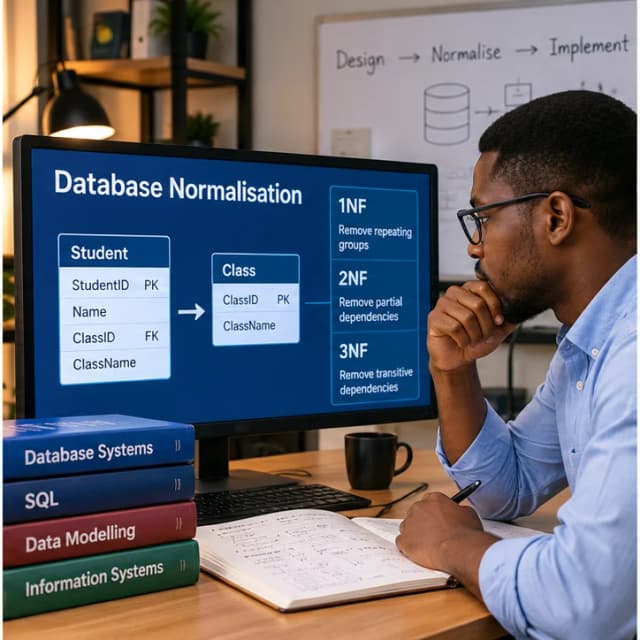
A clear, technically careful introduction to first, second and third normal form, built around a school results database. Learn what functional dependencies are, why update, insertion and deletion anomalies happen, and how to remove them step by step.
In this article
Many school databases begin life as a single spreadsheet: one row per learner, with columns for name, class, class teacher, the teacher's phone number and every subject score. It works well enough until the first time something changes. A teacher gets a new phone number and it has to be corrected in forty places. A new subject cannot be added until someone has a score in it. A learner leaves, and with their row disappears the only record of which teacher was in charge of their class. These are not bugs in the spreadsheet. They are symptoms of a design problem, and normalisation is the standard method for fixing it.
This guide explains the first three normal forms using one running example: a school's end-of-term results. It aims to be precise as well as practical, because several popular shortcuts for explaining normalisation are misleading.
Why normalisation exists
The relational model of data was introduced by Edgar F. Codd in 1970 (Codd, 1970), and the normal forms were developed from it. Their purpose is to organise data so that each fact is stored once. When a fact is stored in many places, those copies can disagree, and some facts cannot be stored at all without inventing others. Normalisation removes these problems by splitting a badly structured table into smaller tables that can be joined back together without losing information.
Two ideas you need first
Functional dependencies
A functional dependency is written X → Y and read "X determines Y". It means that any two rows that have the same value of X must have the same value of Y. For example, if every learner has exactly one name, then LearnerID → LearnerName.
One point is often skipped: functional dependencies come from the rules of the real world, not from the data you happen to have. If your sample contains no two learners with the same name, the data might suggest that LearnerName → LearnerID. But two learners called Kwame Mensah can perfectly well join next term. To find dependencies, ask what the rules of the school are, not what the current rows look like.
Keys
A candidate key is a minimal set of columns that determines every other column in the table. In other words, no two rows can share it, and no column can be removed from it without losing that property. The candidate key chosen to identify rows is the primary key. Columns that belong to any candidate key are called prime columns; the others are non-prime.
The example: a term's results
Here is how the results sheet might look before any design work. (All names and numbers in this article are invented.)
LearnerID  LearnerName   Class  TeacherID  TeacherName  TeacherPhone  Subjects and scores
---------  ------------  -----  ---------  -----------  ------------  -----------------------------
L001       Ama Mensah    B6A    T01        Kofi Asare   000 000 0001  MATH 78, ENG 65, SCI 82
L002       Yaw Boateng   B6A    T01        Kofi Asare   000 000 0001  MATH 54, ENG 70
L003       Esi Owusu     B6B    T02        Akua Darko   000 000 0002  MATH 91
The school's rules are:
Each learner has a unique LearnerID, one name, and belongs to one class this term.
Each class has exactly one class teacher.
Each teacher has a unique TeacherID, one name and one phone number.
Each subject has a unique code and one name (MATH is Mathematics, ENG is English Language, SCI is Science).
A learner receives at most one score per subject this term.
From these rules come the functional dependencies:
LearnerID              → LearnerName, Class
Class                  → TeacherID
TeacherID              → TeacherName, TeacherPhone
SubjectCode            → SubjectName
LearnerID, SubjectCode → Score
First normal form (1NF)
The rule
A table is in first normal form when every value in it is a single value from its column's domain (no lists or repeating groups inside a cell), and every row can be identified by a key.
The sheet above breaks this rule: the last column holds a list of subjects and scores. You cannot easily ask "who scored above 80 in Mathematics?", because the Mathematics score is buried inside a piece of text.
The fix
Give each subject score its own row:
LearnerID  LearnerName  Class  TeacherID  TeacherName  TeacherPhone  SubjectCode  SubjectName       Score
---------  -----------  -----  ---------  -----------  ------------  -----------  ----------------  -----
L001       Ama Mensah   B6A    T01        Kofi Asare   000 000 0001  MATH         Mathematics          78
L001       Ama Mensah   B6A    T01        Kofi Asare   000 000 0001  ENG          English Language     65
L001       Ama Mensah   B6A    T01        Kofi Asare   000 000 0001  SCI          Science              82
L002       Yaw Boateng  B6A    T01        Kofi Asare   000 000 0001  MATH         Mathematics          54
L002       Yaw Boateng  B6A    T01        Kofi Asare   000 000 0001  ENG          English Language     70
L003       Esi Owusu    B6B    T02        Akua Darko   000 000 0002  MATH         Mathematics          91
Using the rules, the candidate key of this table is {LearnerID, SubjectCode}. Together they determine every other column: LearnerID gives the name and class, the class gives the teacher, the teacher gives the name and phone, SubjectCode gives the subject name, and both together give the score. Neither column on its own is enough, because a learner has several scores and a subject has many learners.
A shortcut to avoid
You will often read that 1NF simply means "one value per cell". That is incomplete. A sheet with columns called Subject1, Score1, Subject2, Score2, Subject3, Score3 has one value in every cell, yet it has the same problems as a list in a cell: where do you put a fourth subject, and how do you search for Mathematics when it might be in any of three columns? Strictly, such columns do not break 1NF, but they are a repeating group in disguise, and good design removes them at this same first step.
The anomalies in the 1NF table
The table is now in first normal form, but it still stores some facts many times. That causes three kinds of anomaly.
Update anomaly. Kofi Asare's phone number appears in five rows. If he changes his number and someone updates only three of them, the database now gives two different answers to the question "what is Mr Asare's number?"
Insertion anomaly. The school introduces French (code FRE). It cannot be recorded until a learner has a French score, because every row needs a LearnerID as part of its key. In the same way, a newly posted teacher cannot be recorded until they become a class teacher and that class has results.
Deletion anomaly. Esi Owusu (L003) is the only learner from B6B in the table. If she transfers and her row is deleted, the database loses the fact that Akua Darko is the class teacher of B6B. Similarly, Science appears only in Ama Mensah's results; delete her rows and the subject name disappears.
Each anomaly has the same cause: one table is recording facts about several different things (learners, classes, teachers, subjects and scores) at once.
Second normal form (2NF)
The rule
A table is in second normal form when it is in 1NF and no non-prime column depends on only part of a candidate key. Such a dependency is called a partial dependency.
Our key is {LearnerID, SubjectCode}. Look at the dependencies:
LearnerName and Class depend on LearnerID alone, which is only part of the key. Through Class, so do TeacherID, TeacherName and TeacherPhone.
SubjectName depends on SubjectCode alone, the other part of the key.
Only Score depends on the whole key.
So the table is not in 2NF.
The fix
Move each group of partially dependent columns into a table keyed by the part of the key it depends on:
Learner (key: LearnerID)
LearnerID  LearnerName  Class  TeacherID  TeacherName  TeacherPhone
---------  -----------  -----  ---------  -----------  ------------
L001       Ama Mensah   B6A    T01        Kofi Asare   000 000 0001
L002       Yaw Boateng  B6A    T01        Kofi Asare   000 000 0001
L003       Esi Owusu    B6B    T02        Akua Darko   000 000 0002

Subject (key: SubjectCode)
SubjectCode  SubjectName
-----------  ----------------
MATH         Mathematics
ENG          English Language
SCI          Science

Result (key: LearnerID + SubjectCode)
LearnerID  SubjectCode  Score
---------  -----------  -----
L001       MATH            78
L001       ENG             65
L001       SCI             82
L002       MATH            54
L002       ENG             70
L003       MATH            91
Two anomalies have already eased. French can now be added to the Subject table before anyone has a score in it, and deleting a learner's results no longer deletes subject names.
Notice one useful consequence of the definition: a table whose candidate keys are all single columns is automatically in 2NF, because a single column has no smaller "part". The Learner and Subject tables are in 2NF for exactly that reason.
Third normal form (3NF)
The rule
A table is in third normal form when it is in 2NF and no non-prime column depends on the key only through another non-key column. Such a dependency is called a transitive dependency.
The more precise definition, found in standard textbooks such as Elmasri and Navathe (2016), is: for every non-trivial functional dependency X → A in the table, either X is a superkey (it contains a candidate key) or A is a prime column.
The Learner table breaks this rule. LearnerID → Class, and Class → TeacherID, and TeacherID → TeacherName, TeacherPhone. The teacher's details depend on the learner only because of the learner's class. Class is not a key of this table, so Class → TeacherID is a transitive dependency, and so is TeacherID → TeacherName, TeacherPhone. That is why the phone number still appears twice for Mr Asare, and why deleting Esi Owusu would still lose B6B's class teacher.
The fix
Give classes and teachers tables of their own:
Learner (key: LearnerID)
LearnerID  LearnerName  Class
---------  -----------  -----
L001       Ama Mensah   B6A
L002       Yaw Boateng  B6A
L003       Esi Owusu    B6B

Class (key: Class)
Class  TeacherID
-----  ---------
B6A    T01
B6B    T02

Teacher (key: TeacherID)
TeacherID  TeacherName  TeacherPhone
---------  -----------  ------------
T01        Kofi Asare   000 000 0001
T02        Akua Darko   000 000 0002
Together with Subject and Result from the previous step, the database now has five tables, and every one of them is in third normal form: in each table, every dependency has a key on its left-hand side.
The anomalies are gone:
Update: Mr Asare's phone number is stored once, in the Teacher table.
Insertion: a new teacher can be added to Teacher, and a new subject to Subject, before any results exist.
Deletion: if Esi Owusu leaves, the Class table still records that Akua Darko is the class teacher of B6B.
A memorable summary comes from William Kent's classic guide: under second and third normal form, a non-key field must provide a fact about "the key, the whole key, and nothing but the key" (Kent, 1983). "The whole key" is 2NF; "nothing but the key" is 3NF.
Nothing was lost
Splitting tables is only correct if the original information can be rebuilt. Because each new table shares a key with another, a query can join them back into the full report:
SELECT l.LearnerName, l.Class, t.TeacherName, s.SubjectName, r.Score
FROM Result r
JOIN Learner l ON l.LearnerID = r.LearnerID
JOIN Class c ON c.Class = l.Class
JOIN Teacher t ON t.TeacherID = c.TeacherID
JOIN Subject s ON s.SubjectCode = r.SubjectCode
ORDER BY l.LearnerName, s.SubjectName;
The keys are also what let the database protect itself. For example, the Result table can be defined so that every score must belong to a real learner and a real subject, and no learner can have two scores in the same subject:
CREATE TABLE Result (
  LearnerID   VARCHAR(10) NOT NULL REFERENCES Learner (LearnerID),
  SubjectCode VARCHAR(10) NOT NULL REFERENCES Subject (SubjectCode),
  Score       INTEGER CHECK (Score BETWEEN 0 AND 100),
  PRIMARY KEY (LearnerID, SubjectCode)
);
If the school later stores results for several terms, Term simply becomes part of the key: a learner then has one score per subject per term, and the primary key of Result becomes (LearnerID, SubjectCode, Term).
More misleading shortcuts
"3NF means no non-key column depends on another non-key column." This is close, and it is a fair first approximation, but the precise rule is about non-prime columns and allows a dependency whose right-hand side is part of a candidate key. When a table has more than one candidate key, the difference matters. A stricter form, Boyce–Codd normal form (BCNF), removes even that exception; it is worth learning next.
"Normalisation means splitting tables." Splitting is the method, not the goal. The goal is that each fact is stored once and the original information can still be rebuilt.
"More normalised is always better." For everyday data entry, 3NF is a sound default. But reports, dashboards and data warehouses sometimes combine tables deliberately for speed. That is a conscious trade-off, made after normalising, not an excuse to skip it.
Conclusion
Normalisation is not an academic ritual. It is a practical way of making sure a database tells one consistent story, whether it holds a school's results, a shop's stock or a hospital's appointments. The method is always the same: write down the real-world rules, turn them into functional dependencies, find the keys, and split the tables until every fact depends on the key, the whole key and nothing but the key.
Try this: Take any spreadsheet you use at school or work. Write down the rules it follows, list the functional dependencies, and find its key. Then ask the three anomaly questions: what would I have to change in several places, what can I not record yet, and what would I lose by deleting a row? The answers will tell you how to split it.
References
Codd, E. F. (1970). A relational model of data for large shared data banks. Communications of the ACM, 13(6), 377–387. https://doi.org/10.1145/362384.362685
Elmasri, R. and Navathe, S. B. (2016). Fundamentals of Database Systems (7th ed.). Pearson. Chapter 14, Basics of Functional Dependencies and Normalization for Relational Databases.
Kent, W. (1983). A simple guide to five normal forms in relational database theory. Communications of the ACM, 26(2), 120–125. Author's copy
About the author
Moses Bentum
Moses Bentum is a Ghanaian educator, software developer, and founder of MosTek Solutions. With a background in Science Education and Information Technology, he develops innovative software solutions for schools and businesses. His interests include artificial intelligence, educational technology, data analytics, and digital transformation. Through MosTek Insights, he shares practical knowledge, research perspectives, and technology-driven solutions.
More from Moses Bentum